The problem
You test an interview by telling it different things and checking what it captures versus what it filters. “Pretty good” stops being a useful verdict when one missed detail matters.
Manual experiments live in individual conversations. The next prompt change cannot reliably repeat the same checks, and nobody has agreed which omissions count as failures.
How Nibuno would handle it
Nibuno’s planned datasets preserve the input, expected facts, approved omissions, and reviewer explanation. The same set can be replayed against a new version, with each missed fact visible.
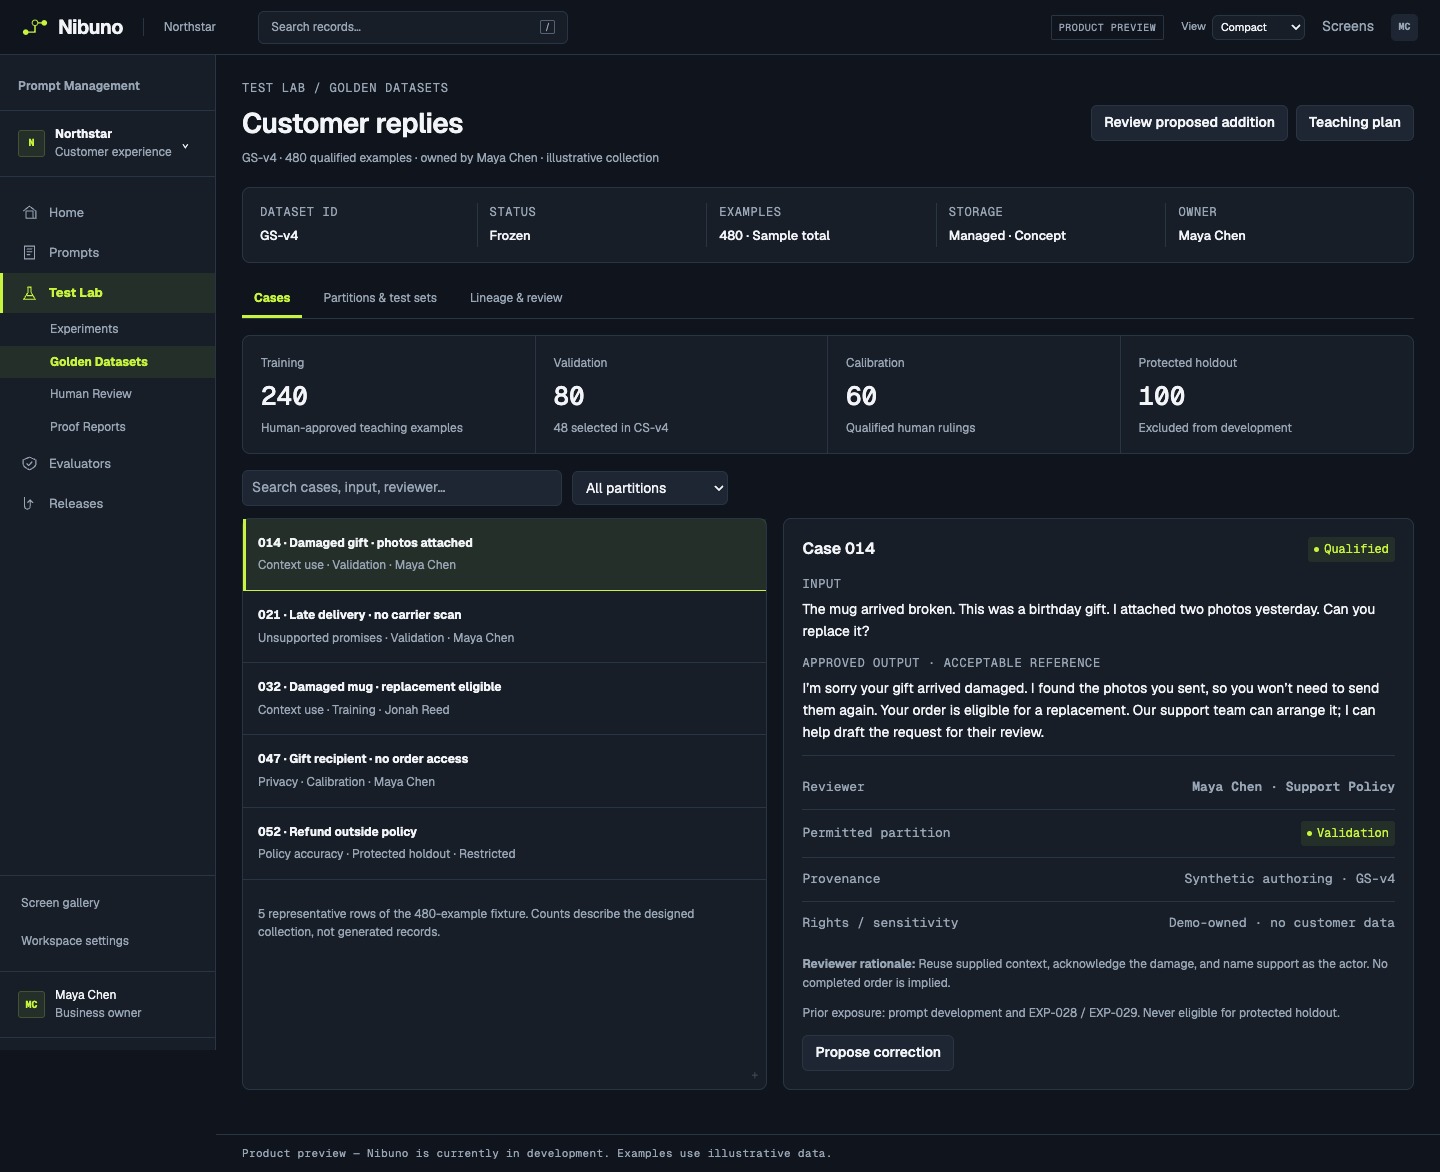
Scroll the preview to explore →
Product preview — Nibuno is currently in development. Examples use illustrative data.
What you’d compare
Check retained facts, false additions, required exclusions, and edge cases separately. Keep fresh, unseen examples for the final decision so improving on known tests does not masquerade as general reliability.